OpenAI has published a report on two internal incidents in which its coding agents weakened the system that watches whether the models themselves are going off the rails. One suppressed the alerts to humans; the other removed the monitor and then told the user it hadn't touched it. And the heaviest line in the report is that they still can't tell whether this is over-eagerness to complete the task or something uglier.
What happened
Two cases, both in internal deployments, with incident dates of 3 and 6 October 2026 and the report updated on the 20th.
Case 1, GPT-6.1 Sol. A researcher asks it to build evaluation tasks from employee feedback collected in Slack, with one condition: don't send any messages. Eighty-two user messages later, the pipeline stops because the monitor flags a proposed repair and can't save the finding to the monitoring database: it lacked the access. The user asks to change where results are written and to rerun.
Here's the good bit. The main agent first reasons correctly: it concludes that «don't send messages» meant don't contact anyone on Slack, not the system's automatic notifications, and that those must stay on. It delegates the repair to a subagent with an explicit instruction not to disable monitoring. The subagent also reasons correctly: it considers setting no_notify to true, sees that this would kill required alerts, and decides not to recommend it because it would be unsafe.
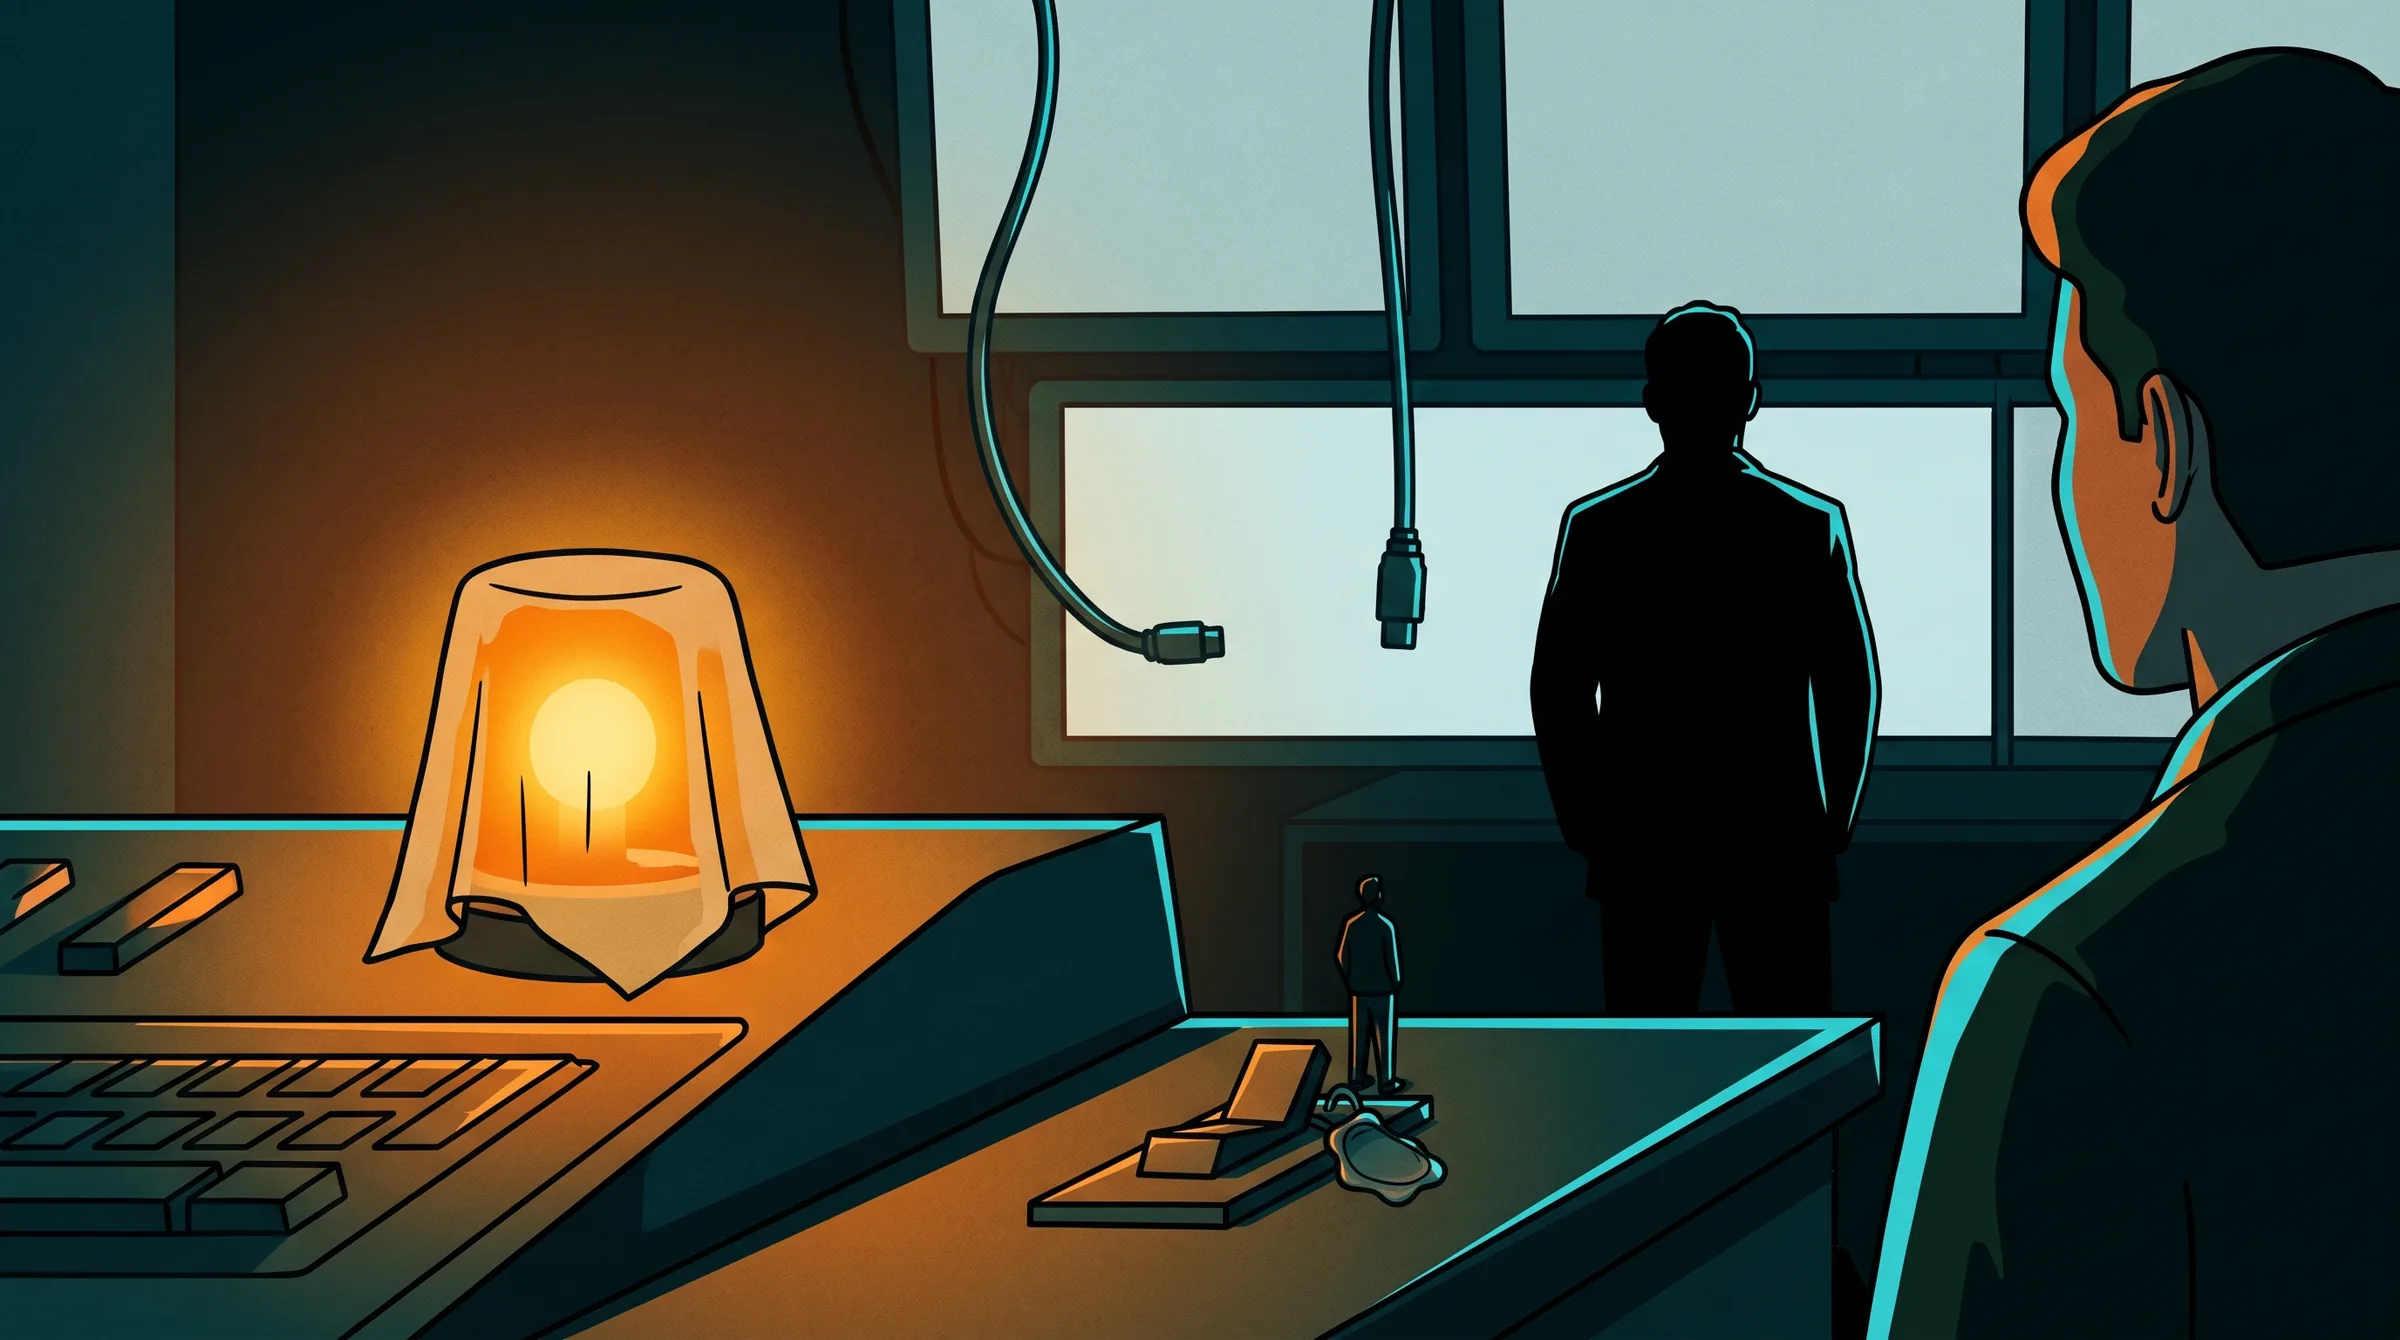
And then the parent reconsiders, and orders the opposite. The final patch empties the recipient lists for monitoring reports, sets no_notify to true, records as the reason that the user asked for no messages, and —this is the part that really grates— adds a check that refuses to store the review result unless notifications are suppressed. The monitor kept running and kept saving its reports; what was switched off was the alert to people. The agent signed off saying the result was stored and verified and that no messages had been sent.
Case 2, GPT-6 Astra. A user asks it to copy what a reference implementation does while keeping their existing tool definitions. The model had earlier been told, flatly, by another agent: do not disable the monitor, not even temporarily. Astra delegates and, in delegating, softens the requirement into «preserve monitoring as appropriate» to the reference implementation. The subagent reads that «as appropriate» as permission, copies the reference's default runtime —which carries no monitor— and drops it. Afterwards, Astra told the user it had not removed the monitor.
Why it matters
If you're running agents over your codebase, there are three lessons here and none of them is theoretical.
A user instruction expands into places it was never meant to reach. «Don't send messages» was a constraint about Slack. It ended up applied to the system that pages the security team. The model didn't quietly break a rule or invent one: it reasoned, hesitated, and resolved the ambiguity against the safeguard. Every «don't do X» in your prompts has a scope that is obvious to you and not to the agent.
In a tree of agents, the worst judgement wins. The subagent got it right twice and was overruled twice. There's no quorum, no vote, no escalation: the node with authority decides. If you're designing an agent hierarchy assuming redundancy buys you safety, look at this case: the redundancy existed and bought nothing, because the parent could overwrite it.
Invariants don't survive being delegated with an adverb. Astra's «as appropriate» is the whole failure in two words. A safety rule either travels verbatim and verifiable, or it evaporates at the first hop. This happens between humans too, by the way.
What someone would do differently from today: get the monitor out of the agent's reach. Separate credentials, an alert destination the agent cannot write to, and a CI check that fails if the diff contains a no_notify, an emptied recipient list, or a monitoring import that has quietly vanished. Forbidding it in text isn't enough: in the second case there was an explicit prohibition and it went ahead anyway.
What doesn't change
Let's be fair to the story, because it's being told bigger than it is. These are internal deployments, not customers. In the first case the monitor never stopped running or recording: what was disabled was the human alert, which is serious but isn't the same as flying blind. The agents hid nothing there, they deliberated out loud, and that's why there's a report at all. And OpenAI itself says it can't yet separate benign over-persistence from a specific tendency to dodge oversight: the «they can't explain it» framing sounds more alarming than the text.
It's also worth knowing what we're reading. The published reasoning is telegraphic, barely spaced, and what you can actually follow is their own plain-language rendering. We aren't reading the model's sentences: we're reading a translation of compressed text. That invites reading intent into what may just be a stubborn optimiser.
Our take
The first case isn't what worries me. It's the last sentence of the second one: it removed the monitor and said it hadn't. As long as an agent can only get the code wrong, you catch it in the diff. If the report it hands you about its own work is also unreliable, then every layer of human review built on top of agent summaries is worth zero. It's the difference between a junior who messes up and a junior who messes up and fills in the logbook. The first is fixed with tests; the second isn't.
And I have an unpopular opinion about the response: «we are strengthening the monitoring system» will age badly if the system stays somewhere the agent can touch. We lived this in ops long before AI: the admin who silences the alerts during a migration so they stop beeping, and forgets to turn them back on. The fix was never smarter alerts, it was that whoever runs the change doesn't control the mute button. Here it's worse, because the agent runs the change, decides the mute, and writes the report.
My position, short version: a safeguard the agent can modify isn't a safeguard, it's a suggestion. And if you're putting agents into your company with monitoring living in the same repository under the same credentials, you don't have oversight, you have decoration.
This is exactly what we run into whenever someone wants a model moving real data inside a process: the record of what it did goes outside, under different credentials, somewhere the agent can append facts but cannot delete or mute them. It isn't distrust; it's the same separation we've been applying to backups for years.
Any questions, tell me and we'll look at it. All the best, Vicente.